Enterprise AI
Jev does not chat—it evaluates: where it fits and how to connect it
We normally ask generative models to write, summarise or explain. Jev targets a different gap: given a state, return a constrained, typed decision together with probabilities. That difference may sound small, but it changes how the surrounding product should be designed.
What Jev is—and is not
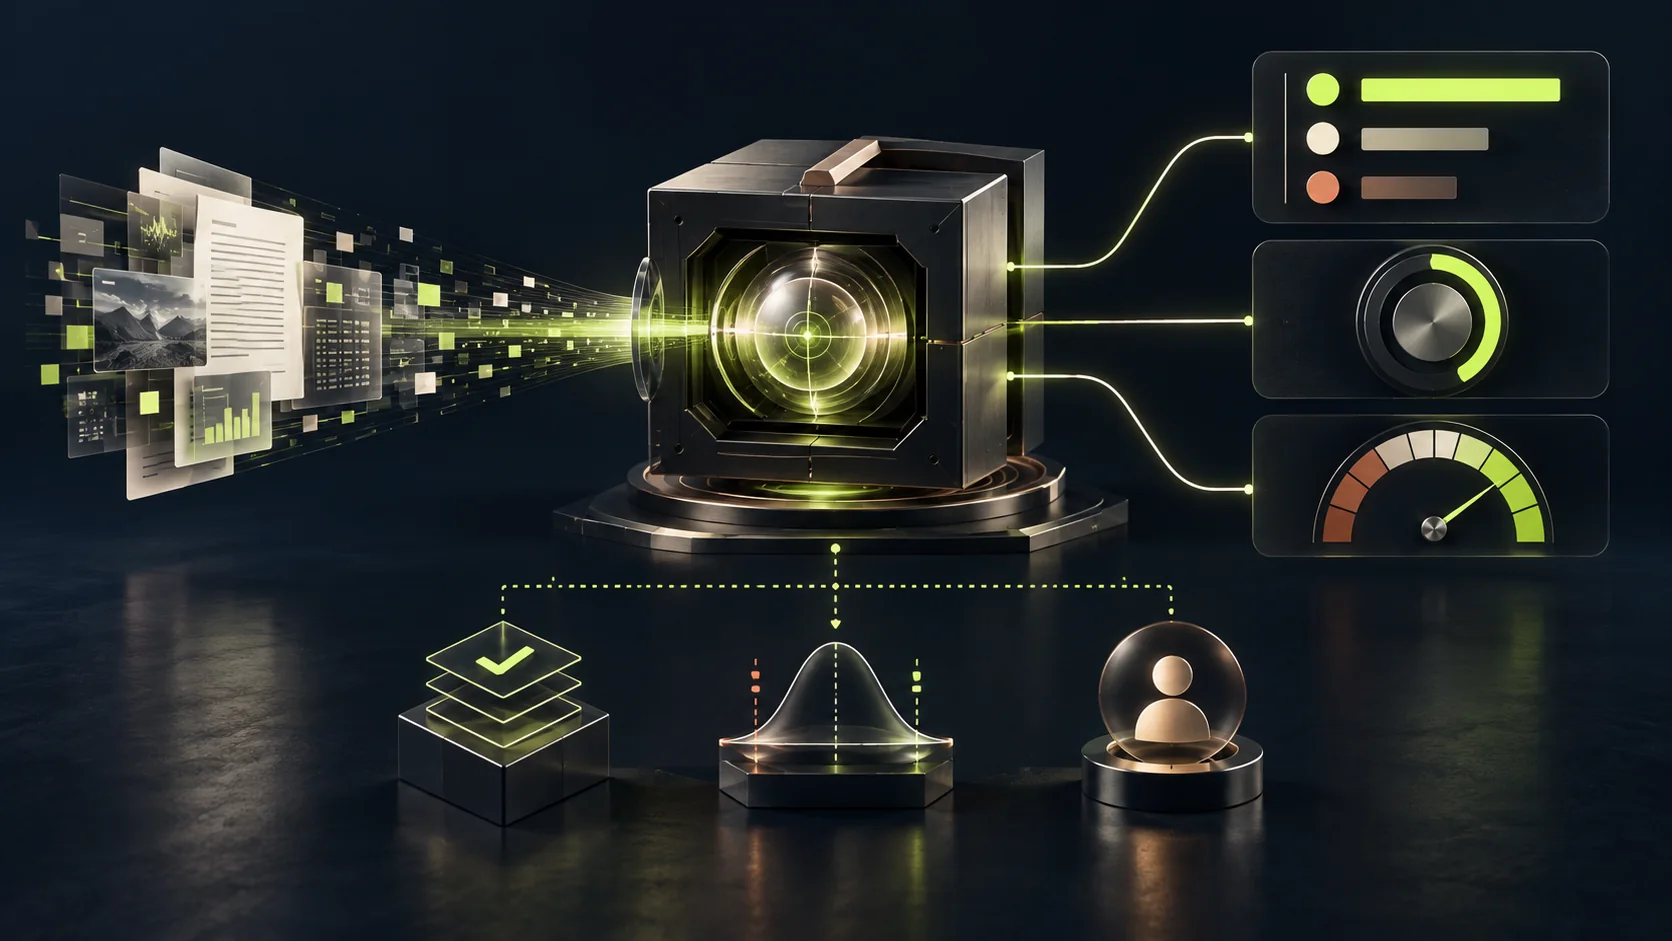
Jev is the System One evaluation model TypeSafe AI released in early access on 15 September 2026. It does not generate free-form prose, chat, write code or draft explanations. It takes a shared state plus predefined questions and returns structured results.
There are three core output types. Choice ranks options with probabilities. Score produces a value and distribution within a defined range. Noul returns a boolean-like probability between zero and one. Several questions can be evaluated independently and in parallel against the same state.
Do not confuse it with the whole decision engine
A Jev result does not need to become the application’s final decision. A safer pattern is for the model to produce an evaluation and confidence while thresholds, business rules and side effects remain in ordinary application code. Routing a low-confidence classification to a person, or requiring a second review above a risk threshold, is still a product decision.
TypeSafe says Jev cannot hallucinate because it does not emit free-form text outside the schema. That should not be read as “it cannot make a wrong judgement”. The output shape can be guaranteed; incomplete inputs, badly framed questions and model error remain possible.
Where does it fit?
Routing a support request, assigning priority or risk, classifying content or transactions, and adding a gate before automation are natural candidates. The same context can be evaluated for “which team?”, “how urgent?” and “does this require human approval?” at once.
Jev is the wrong tool for producing a customer response, report, email or explanation. In such a flow, a generative model such as Qwen can compose the text while Jev evaluates only defined decision points. The two models need not compete; they can perform different jobs.
How do you connect it?
For direct access, obtain an API key from TypeSafe Console and use the official Python or JavaScript/TypeScript SDK against `https://api.typesafe.ai/v1/systemone`. The application defines the state and typed questions; Jev returns the structured answer.
Vercel AI Gateway also exposes it as `typesafe-ai/jev` through AI SDK 7’s `experimental_evaluate` call. The important distinction is that Jev is not a Vercel model. Vercel provides an access and billing layer to TypeSafe’s service. Production monitoring should preserve that distinction across provider, data path, error behaviour and pricing.
Can it run locally?
Official Jev weights are not published today, and there is no documented self-hosted inference path. Your Python or JavaScript application can run on your own machine, but the evaluation request travels to TypeSafe, directly or through Vercel AI Gateway. A local client is not a local model.
Open-source client SDKs do not make the model weights open. If data boundaries, latency or an external-service dependency are unacceptable, Jev may not fit today. If they are acceptable, the first step should still be a small evaluation of atomic questions, confidence calibration, latency and failure cases—not handing over a production process.